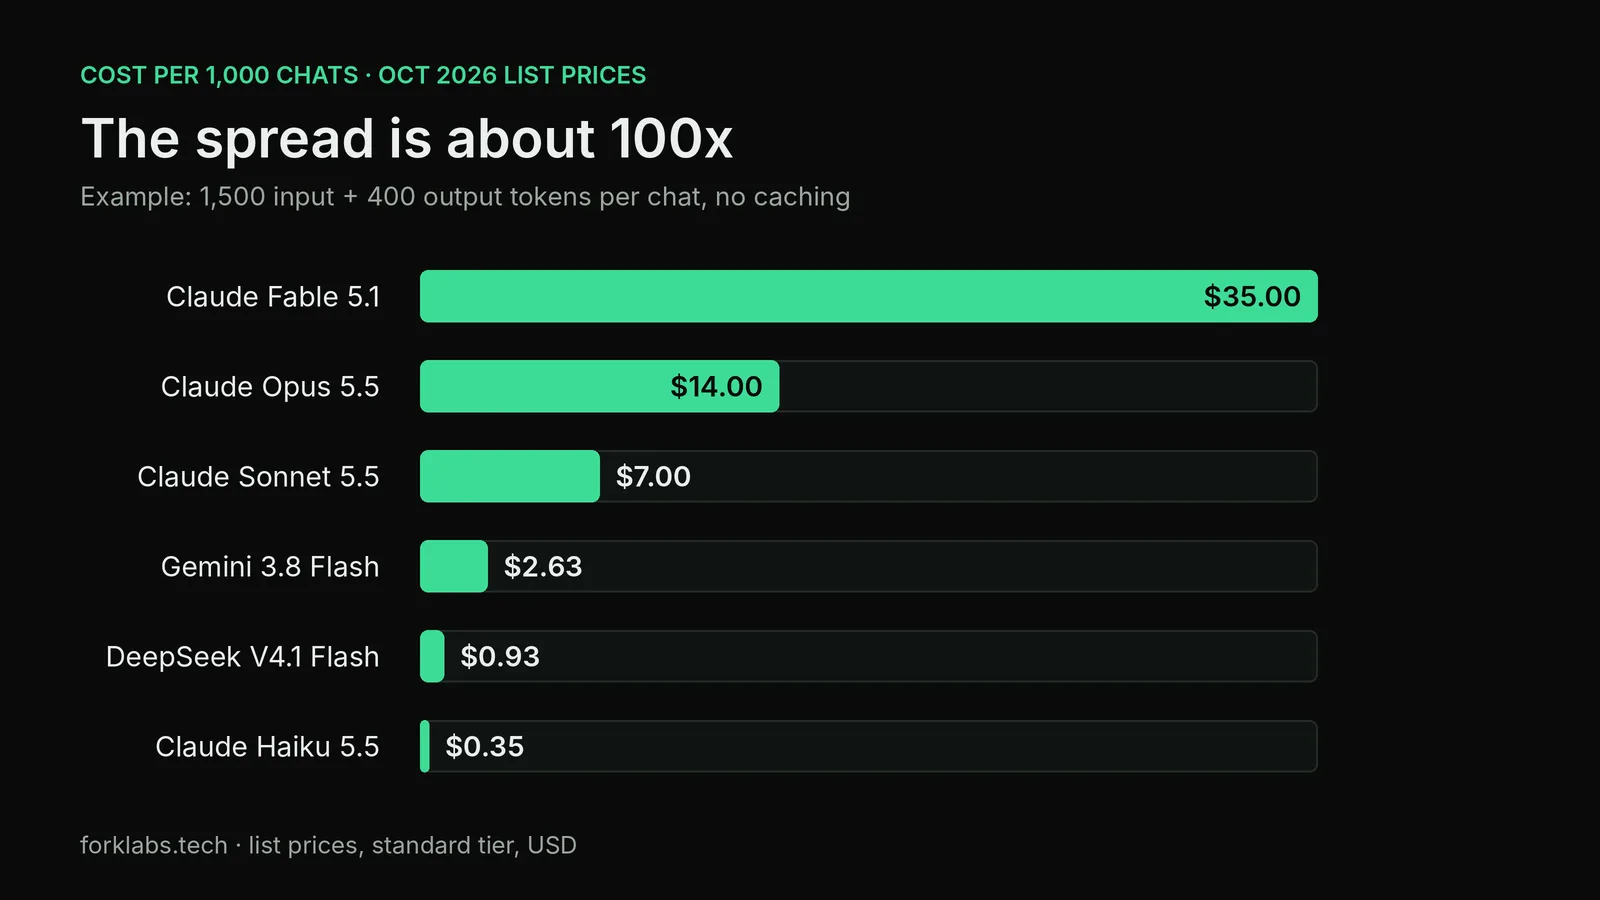
Per-million-token prices are hard to compare in your head, and they rarely map to what a product owner asks: what will 10,000 customer chats cost us per month? This post converts the published list prices of four vendors into cost per 1,000 chats, using one stated assumption, so you can sanity-check a quote or a budget.
Prices below were read from each vendor's own pricing page on October 20, 2026. Vendors change prices often, so treat this as a dated snapshot, not a reference. The data is also available as a CSV.
The assumption
One chat is 1,500 input tokens and 400 output tokens. That is an example for a support-style assistant with a system prompt, a few retrieved passages and a short answer. It is not a measurement from any real deployment. Replace it with your own numbers; the formula is simple:
cost per 1,000 chats = 1,000 × (input_tokens × input_price + output_tokens × output_price) / 1,000,000
All prices are standard-tier list prices in USD per million tokens. The estimates exclude batch discounts, reasoning or thinking tokens beyond what is in your output count, tool calls, embeddings, retrieval and hosting.
Cost per 1,000 chats, no caching
| Vendor | Model | Input / output per 1M | Per 1,000 chats |
|---|---|---|---|
| Anthropic | Claude Fable 5.1 | $10 / $50 | $35.00 |
| Anthropic | Claude Opus 5.5 | $4 / $20 | $14.00 |
| Anthropic | Claude Sonnet 5.5 | $2 / $10 | $7.00 |
| Anthropic | Claude Haiku 5.5 (prompts up to 100K) | $0.10 / $0.50 | $0.35 |
| OpenAI | GPT-6 Astra | $10 / $50 | $35.00 |
| OpenAI | GPT-6.1 Sol | $2 / $10 | $7.00 |
| OpenAI | GPT-6 Luna | $0.10 / $0.50 | $0.35 |
| Gemini 3.1 Pro Preview (up to 200K) | $2 / $12 | $7.80 | |
| Gemini 3.8 Flash (introductory) | $0.75 / $3.75 | $2.63 | |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | $1.45 | |
| DeepSeek | V4.1 Flash, peak | $0.30 / $1.20 | $0.93 |
| DeepSeek | V4.1 Flash, off-peak | $0.15 / $0.60 | $0.47 |
Sources: Anthropic pricing, OpenAI pricing, Gemini API pricing and DeepSeek pricing.
A few patterns stand out. The spread between the cheapest and most expensive rows is about 100x, so model choice moves your bill far more than prompt trimming does. The flagship tiers of Anthropic and OpenAI list identical prices ($10 / $50) at the top end, and their mid tiers (Sonnet 5.5 and GPT-6.1 Sol at $2 / $10) also match. And output tokens cost five times input tokens on most of these rows, so a chatty answer costs more than a long prompt.
What caching changes
If part of every prompt repeats, such as a system prompt and fixed instructions, cached input is billed far lower. Suppose 1,000 of the 1,500 input tokens are a cached prefix:
| Model | No cache | 1,000 tokens cached |
|---|---|---|
| Claude Sonnet 5.5 (cache read $0.10) | $7.00 | $5.10 |
| Claude Haiku 5.5 (cache read $0.01) | $0.35 | $0.26 |
| GPT-6.1 Sol (cached input $0.10) | $7.00 | $5.10 |
| Gemini 3.8 Flash (cached $0.075) | $2.63 | $1.95 |
| DeepSeek V4.1 Flash, peak (cache hit $0.006) | $0.93 | $0.64 |
Two caveats. Anthropic charges more than the base input price to write a cache entry ($2.50 per million for the 5-minute cache on Sonnet 5.5, against $2 base), so a prefix that is rarely reused saves less than this table suggests. And Gemini bills cache storage separately, per million tokens per hour, which the table leaves out. Caching helps most when the same prefix is hit many times within the cache window.
Because output dominates the bill in this example, caching saves around a quarter to a third here. It would matter more for long prompts and short answers, such as document question answering.
Price changes already on the calendar
- Gemini 3.8 and 3.6 Flash list introductory prices that end on December 31, 2026. From January 1, 2027 the listed prices double to $1.50 input and $7.50 output, which takes our example from $2.63 to $5.25 per 1,000 chats.
- Gemini 4 Argon lists $2 / $10 until November 30, 2026, then $4 / $20 from December 1.
- DeepSeek charges half price off-peak. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, excluding Chinese public holidays. A batch or background workload can be scheduled into the cheaper window.
- Long prompts cost more on several models. Haiku 5.5 rises to $0.50 / $2.50 above 100K prompt tokens, GPT-6.1 Sol lists a higher long-context rate, and Gemini 3.1 Pro doubles input above 200K.
If you are budgeting past January, price the post-promotion rate, not the introductory one.
How to use these numbers
- Measure your real token counts per conversation from a week of logs before trusting any estimate. Multi-turn chats resend history, so input tokens often grow faster than you expect.
- Pick the cheapest model that passes your own evaluation set, then re-run the comparison when prices change. Quality gaps between tiers are task-specific; this post compares prices only.
- Add the costs this table leaves out: retrieval, embeddings, a vector store, monitoring and engineering time. In an earlier RAG build on Pinecone, ChromaDB and Weaviate, those pieces mattered alongside the model bill.
- Put the price date in your budget document. A quote from three months ago may already be wrong.
Cite and reuse
You may reuse these figures with credit. Suggested citation: Fork Labs, "LLM API pricing in October 2026 with cost per 1,000 chats", forklabs.tech/blog/llm-api-pricing-october-2026-cost-per-1000-chats, October 20, 2026. Spotted a wrong or stale price? Tell us and we will correct it.